Scroll back through a Claude Code session and try to answer a simple question: how long did that refactor take?
You get fragments. Claude Code ends a turn with a line like ✻ Sautéed for 23s · done 6:05 PM. Ctrl+O opens the transcript viewer, with a timestamp on each assistant message. And the session block in /usage, meant for API users, gives a total duration.
None of the three answers your question. A refactor of nine turns is nine lines to go and find, and nothing says how much of that time was the agent and how much was you at lunch.
The first version of this post claimed nothing on the screen tells you. Claude Code was already showing the duration, which is a fine mistake to make in a post about not paying attention.
I noticed the gap about twenty times before I did anything about it. Usually while trying to reconstruct an afternoon for an invoice, or answering "did that actually get faster?" with a shrug.
So I built the clock
Timestamps (formerly claude-timestamp) is a plugin for Claude Code and Codex. In Claude Code it puts a marker in front of every assistant message: local time, and how long the turn took from the moment you pressed enter. The tool page walks through the features, client support and configuration.
[13:22:13 +2m14s] I've updated the migration and re-run the suite.Once a turn crosses a threshold you set, the duration changes colour, so a slow turn catches your eye on the way past. Step away for an hour and the gap gets labelled on its own line, which means a session you returned to the next morning still reads in order. On exit it reports what the session cost:
Session lasted 1h30m over 12 turns, 24m18s of it waiting, 35m00s away.
slowest tools: Bash 41.2s (18 calls), WebFetch 8.1s (1 call), Read 2.0s (37 calls). 2 failedInstall is two commands. Start a new session afterwards, because hooks are bound when a session starts.
claude plugin marketplace add https://github.com/AraneaDev/aranea-marketplace
claude plugin install timestamps@araneaThe dependency list is jq and bash, and /timestamps:configure tokyo or /timestamps:configure 12 hour clock changes settings from inside the session without restarting anything.
Codex has no event for drawing on a message, so it gets no marker there. It does get the notes for the agent, the history and the totals.
The second line of that session report needs TOOL_TIMING, which is off by default. It is one of four settings that cost something per tool call, a few milliseconds on the machine it was measured on. The other three stay on, because the agent's notes depend on them.
The model can't tell you either
The agent has no sense of elapsed time, which surprised me more.
A conversation, to the model, is a list of messages with no times attached. It knows today's date, because Claude Code tells it. It has no idea whether your previous message arrived thirty seconds ago or last Tuesday.
Ask it how long that last Bash command took and it will guess, confidently, the way it guesses everything else. Claude Code does measure the duration, but it hands the number to hooks. The context window is a transcript, and a transcript is timeless.
The exceptions are narrow. A subagent's result carries its duration, a memory file carries when Claude last wrote it, and the agent can always run date. That tells it the time now, and nothing about how long anything took.
So when you ask an agent to reason about time, you are asking a system with no world model to reason about a dimension it only ever gets scraps of.
Both ends of the conversation are flying blind on this. You have a duration per turn and your memory of the rest. The model has less.
Two hooks, two audiences
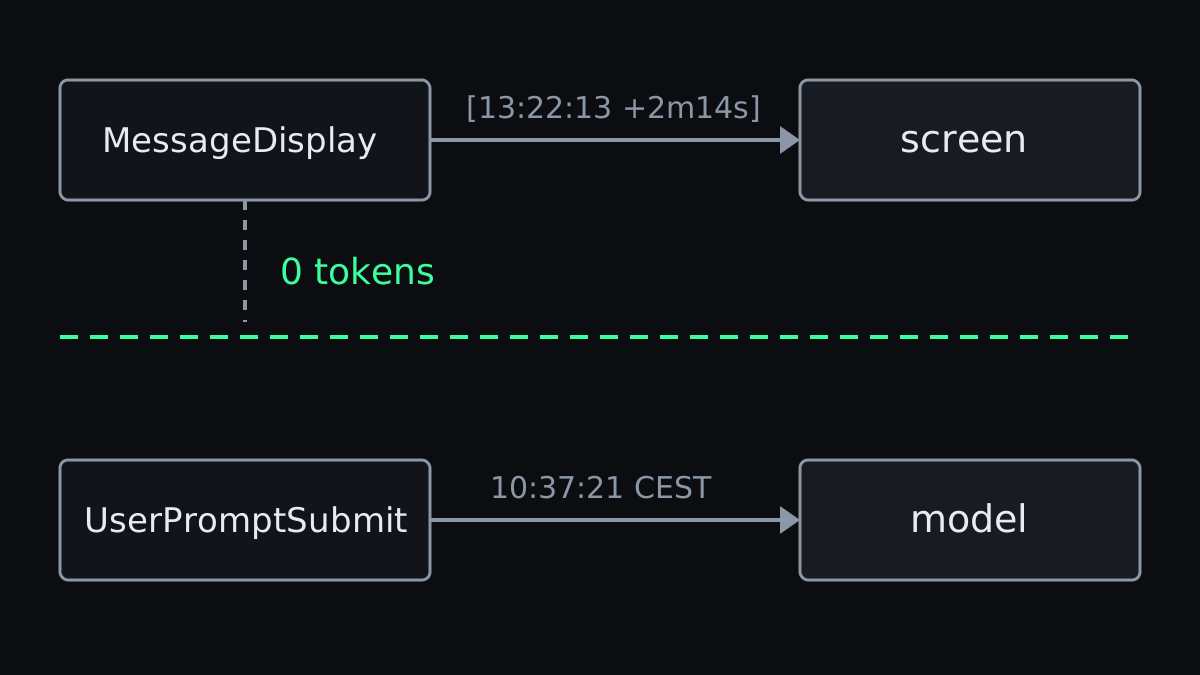
The design point worth stealing has nothing to do with clocks.
The marker you see is drawn by a MessageDisplay hook, which Claude Code documents as display-only. It replaces what is painted on your screen and leaves the stored transcript and the model's view untouched. So the timestamps cannot confuse Claude, cannot be misread as part of its own output, and cost zero context.
The time the model gets is a separate channel: a UserPromptSubmit hook that adds one line saying when the prompt was sent. That one does reach the model, appended as context rather than folded into what you typed, so it reads as metadata. It leaves the date out, since the model already gets that from Claude Code and paying tokens for it twice would be silly.
That channel has grown since August. The agent now hears when a turn runs past fifteen minutes, when a tool call takes a minute or more, and how long a slow command usually takes in this project:
That Bash call took 6m10s (usually 4m02s).The notes state facts and give no instructions. What the agent should do with them lives in a bundled skill.
Those are deliberately different mechanisms for deliberately different readers, and either can be switched off without touching the other. If you have ever wondered which mechanism to reach for, this is a clean example of the answer being "both, for different jobs". The hooks guide covers the lifecycle they hang off.
One implementation note, because it took me a while to get right. MessageDisplay fires repeatedly as a message streams, once per batch of completed lines. Only the first batch gets stamped. The rest return nothing at all, which the docs define as the way to leave the original text on screen.
Echoing the text back unchanged would have been a wasted round trip on every batch of every message, which is a strange way to pay for a feature that exists to tell you where your time goes.
Nobody is measuring, including the people measuring
This matters more than a missing timestamp usually would, because the entire argument about whether coding agents make you faster runs on self-report.
METR published the number everyone quotes: experienced open-source developers took 19% longer with AI tools while believing they had been sped up by 20%. That result is from early 2025, and METR has since marked it out of date itself, with a continuation published in February 2026. Worth knowing before you cite it at your next stand-up.
The new estimate matters less than why METR calls its own data "an unreliable signal". The main reason is developers who no longer want to work without AI. But the February 2026 update also calls its time measurements "unreliable for the fraction of developers who use multiple AI agents concurrently", and lists this among the less severe problems: "Some developers reported it was challenging to report time-spent in completing tasks when they used agentic tools, because they would often work an unrelated task while waiting for the agent to complete its work."
A research organisation running a controlled experiment, paying developers $50 an hour, could not get reliable time data from everyone using agents. Because people wander off while the agent works. That is exactly what you do, and nobody is paying you $50 an hour to write it down.
Everything anyone tells you about agent speed, including what you tell yourself, is a memory of watching a spinner.
What the numbers are, and what they aren't
When this post first went out I had exactly one recorded session, because the history file was written that afternoon: 27 minutes, five turns, ten and a half minutes of it waiting. Almost 40% of that session was me watching a cursor.
One session proves nothing. That is rather the point. So I closed with a promise: ask me in a month and I will have a number.
It took almost seven weeks, and the number came from a month of my own sessions: 74 hours generating against 117 hours waiting on tools. That is more than anyone arguing about agent productivity on the internet usually has.
Be careful what you do with it, though. Wall-clock waiting is not productivity, and the summary cannot tell you whether the agent helped. A turn that took four minutes and produced a correct migration beats one that took twenty seconds and produced a plausible mess. If you turn "time waiting" into a number you optimise, you have reinvented measuring the wrong thing with a different unit.
What it does tell you is where your attention went. Which sessions had you sitting there. Which tools eat the wall clock. Whether the afternoon that felt productive was thirty minutes of work and two hours of waiting, or the other way round.
The clock does not make you faster. It just stops you guessing.